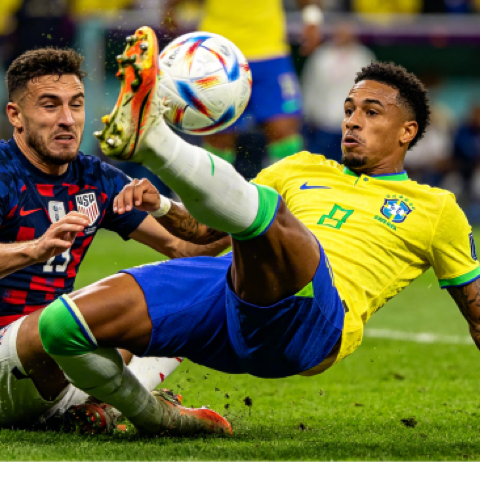
SPORTS
30s
Stadium Goal Commentary
Inside a huge football stadium, tens of thousands of fans roar throughout the background, swelling whenever the action peaks.
SeedAudio 1.5 generates dialogue, music, ambience, and sound effects in one pass. Coming soon — try Seed Audio 1.0 now and lock in early-bird pricing.
SeedAudio 1.5
Live scene mix
Scene brief
A midnight radio booth: the host signs off in a low voice, vinyl crackle, rain on the glass, and a last piano sting before the carrier tone.
Create dialogue, music, ambience, and sound effects from a prompt. This live workspace runs Seed Audio 1.0.
Input
Prompt-first audio generation with optional controls.
Additional Settings
Customize your input with more control.
History
Your recent Seed Audio 1.0 generations.
Sign in to see your generation history.
Explore tested multi-layer prompt formulas combining character dialogue, environmental beds, foley actions, and musical cues. Click any card to load it into the workspace.
Inside a huge football stadium, tens of thousands of fans roar throughout the background, swelling whenever the action peaks.
A night of pounding rain inside a dim apartment lit by a single lamp; no music, only rain, wind, phone static, footsteps, silence, and the final lock click.
Upbeat podcast intro music fades in clearly, then sits quietly under the voices.
The ad narrator is a young man around thirty years old, with a deep, magnetic, slightly husky voice, speaking Mandarin with clear articulation.
SeedAudio 1.5
SeedAudio 1.5 is ByteDance Seed’s next audio model for complete scenes. seed audio 1.5 is built to generate dialogue, music, ambience, and sound effects together, with reference-guided voices, video-aware dubbing, timestamp control, and separate tracks.
Compared with Seed Audio 1.0, the published seed-audio-1.5 spec raises output from two minutes to six and audio references from three to six. Input modes are text, text plus audio, text plus video, and text plus audio plus video. The online generator still uses Seed Audio 1.0 until SeedAudio 1.5 launches.
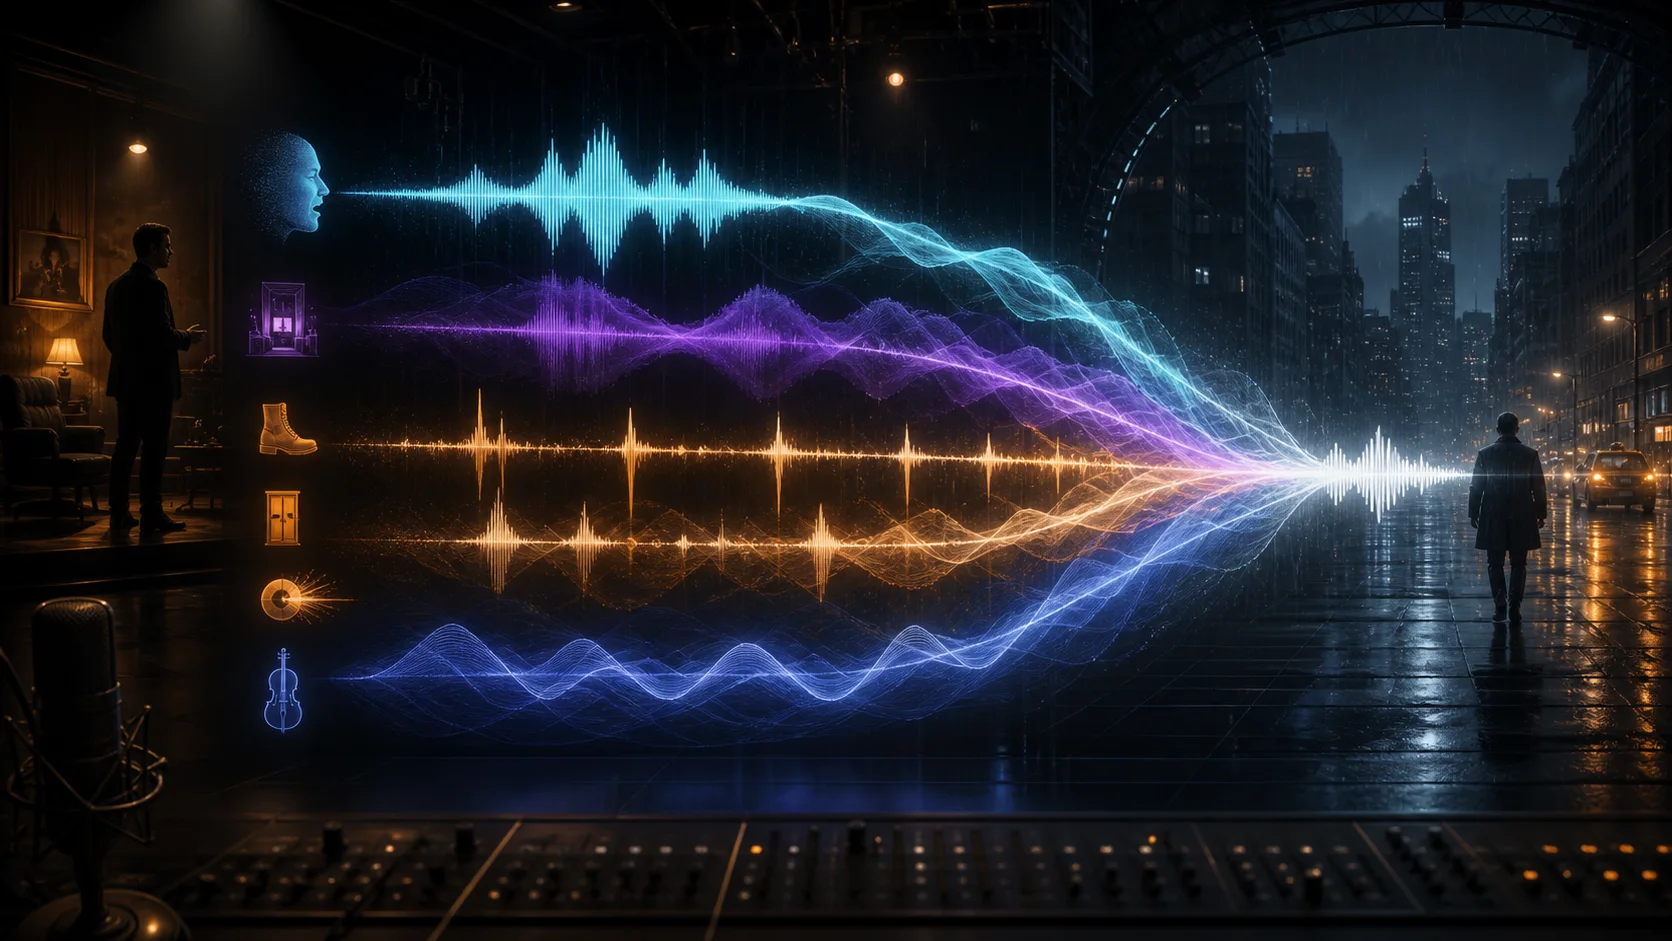
Dialogue
Voices & emotion
Ambience
Room & environment
SFX / Foley
Actions & sync
Music
Score & soundtrack
Inputs
4 Modes: T2A · TA2A · TV2A · TAV2AText, audio, and video across four published input modes
Sound layers
Separate Stem TracksDialogue, ambience, effects, and music, including separate tracks
Output
Up to 6 Minutes · 6 VoicesUp to six minutes once SeedAudio 1.5 is live
Four briefs, four finished scenes
Each clip below began as one written brief that describes dialogue, ambience, effects, and music together. They were rendered with the Seed Audio 1.0 engine that runs on this site today, so you can hear the scene-first approach that 1.5 builds on.
A stall owner, a customer, a sizzling griddle, and a crowd, all inside one brief. A good fit for audio dramas and short videos that need a place to feel alive.
A night food market by the sea. A cheerful stall owner and a young customer trade lines over a sizzling griddle, with far-off scooters, creaking lanterns, and a quiet ukulele underneath.
Night Market Order
0:15
One narrator, a kitchen full of small sounds, and a gentle guitar bed. It shows how voice-over and music can be directed together instead of mixed afterward.
A 15-second spot for a fictional coffee roaster. A relaxed female narrator, a kettle pouring, a mug set on wood, and a soft acoustic guitar that rises under the final line.
Cedar Lane Morning
0:15
Character dialogue with fire, wind, and a distant lute behind it. The kind of scene a game or interactive story needs sketched before final audio production.
A mountain tavern in a snowstorm. A gruff innkeeper tells a nervous traveler the pass is closed, over a crackling hearth, wind on the shutters, and a slow lute in the corner.
The Pass Is Closed
0:18
The same gallery narration written once in English and once in Chinese, each with its own footsteps and quiet room tone. Switch tabs to compare.
A calm audio guide for the third gallery of a history museum. A composed female guide, soft footsteps on stone, hushed visitors in the distance, and a barely audible ambient pad with one cello note.
Gallery Three · English
0:14Version guide
Seed Audio 1.0 already renders mixed sound scenes on this site. SeedAudio 1.5 is the upcoming release that pushes the same idea further: longer output, more references, video input, and stems you can mix yourself.
| Capability | SeedAudio 1.5 (coming soon) | Seed Audio 1.0 (live now) |
|---|---|---|
| Availability | Coming soon. Early-bird orders are open now. | Live. Sign in and generate from the workspace above. |
| Maximum length | Up to 6 minutes | Up to 2 minutes per generation on paid plans; free previews stay around 8 seconds |
| Reference audio | Up to 6 audio references | Up to 3 voice or audio references, or one reference image (not both) |
| Input modes | Text; text + audio; text + video; text + audio + video | A text prompt, optional reference audio, or one reference image |
| Languages | 30 languages with regional variants | Multilingual dialogue and accents, steered through the prompt |
| Video-aware dubbing | Video can be an input, so voice and effects can follow the picture | Not available; video is not an input |
| Timing control | Timestamp instructions for dialogue, effects, and music | Timing is described in the prompt; length is not a hard parameter |
| Output | Separate dialogue, ambience, effects, and music tracks | One mixed file in MP3, WAV, PCM, or Ogg Opus |
| Best for | Long-form dubbing, episode-length narration, and projects that need stems for a final mix | Short scenes, ad spots, game drafts, and testing prompts before a bigger job |
| What to do now | Place an order to lock in early-bird pricing | Write a prompt, listen, revise, and keep your best prompts for 1.5 |
SeedAudio 1.5 figures are published specifications and may change at launch. Until then, the generator on this page runs Seed Audio 1.0.
seed-audio-1.5
Published SeedAudio 1.5 capabilities cover multi-speaker dialogue, reference voices, 30 languages, video-aware dubbing, timestamps, and separate tracks for dialogue, ambience, effects, and music.
6 minutes
published maximum, up from 2 minutes in 1.0
4 input modes
text, audio, and video combinations
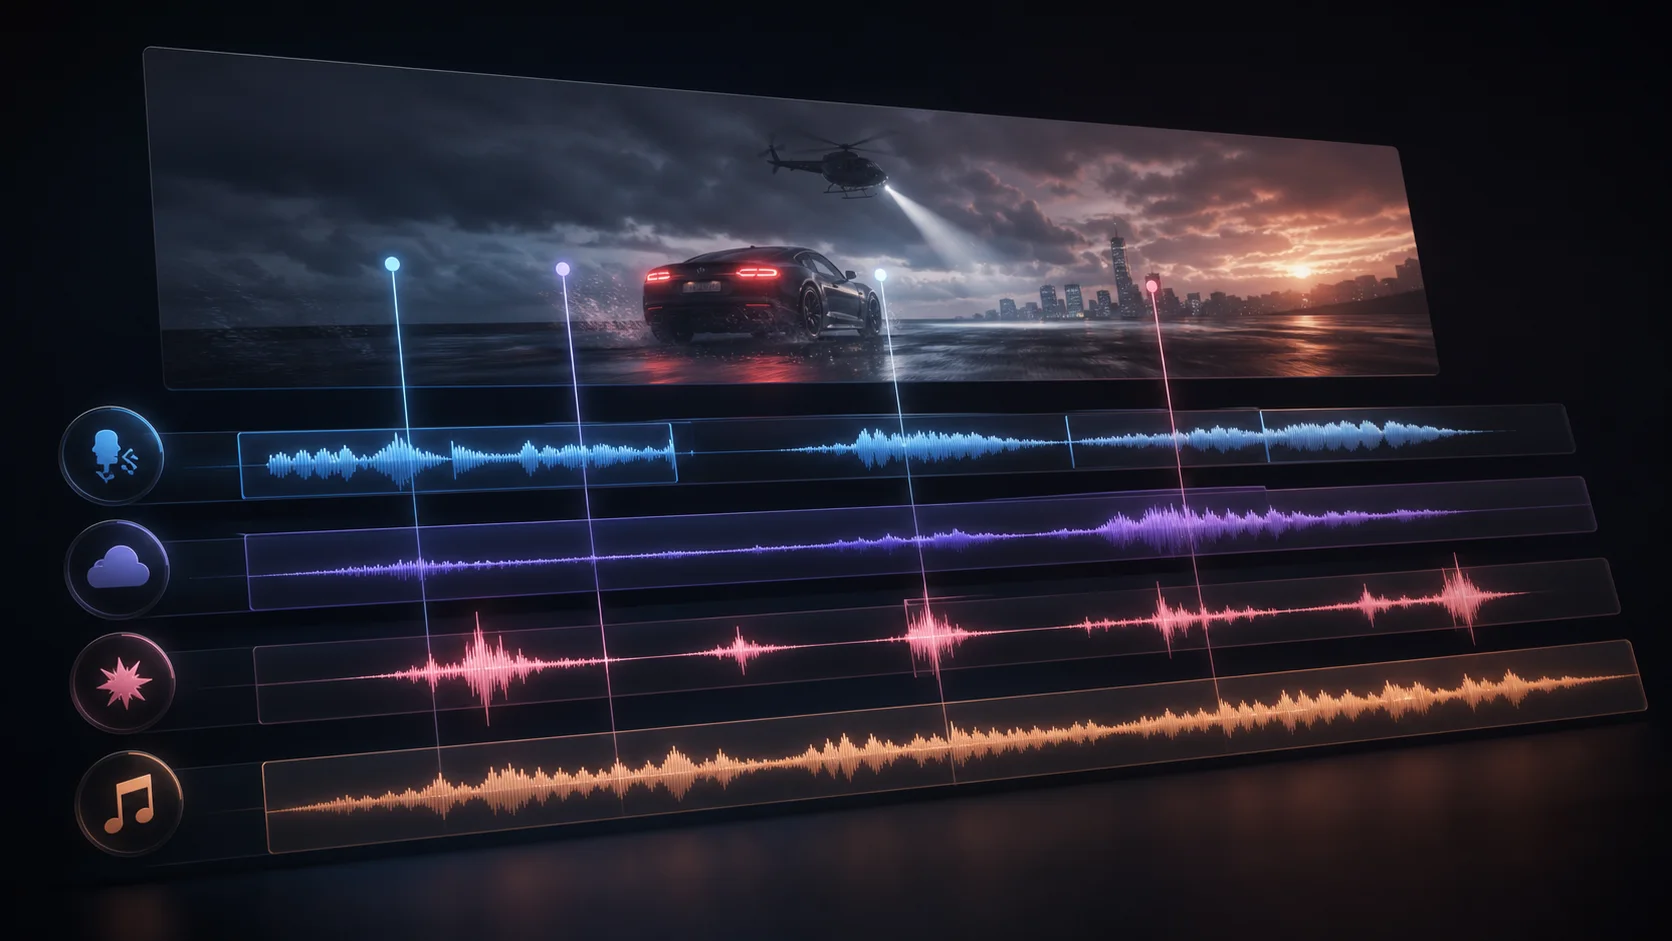
Compose multiple sound layers at once instead of stitching voice, music, ambience, and effects in separate tools.
Reference-guided voices can follow emotion, style, pace, and non-speech sounds. Published support is up to six audio references.
Generate environmental beds, background music, room tone, weather, crowds, or distant city texture alongside the dialogue.
SeedAudio 1.5 raises the published generation length from two minutes to six, with room for longer scenes, narration, and dubbing.
Creative possibilities
seed audio 1.5 is aimed at video dubbing, podcasts, audiobooks, game scenes, and ads that need dialogue, ambience, effects, and music together.
Draft dialogue, emotional beats, foley, ambience, and music for storyboards or pre-visualization.
Create campaign-ready sound directions for product demos, social clips, and localized ads.
Prototype ambient loops, character barks, UI sounds, and cinematic moments before a final audio pass.
Build scenario-based lessons, character conversations, and immersive explainers with spatial sound cues.
Multi-character delivery with emotional tone
Rain, traffic, rooms, crowds, and natural beds
Footsteps, impacts, doors, texture, and timing
How to use
Write a sound-scene prompt, add an optional audio or image reference, choose output settings, then generate. Ordering now keeps early-bird pricing for seed-audio-1.5.
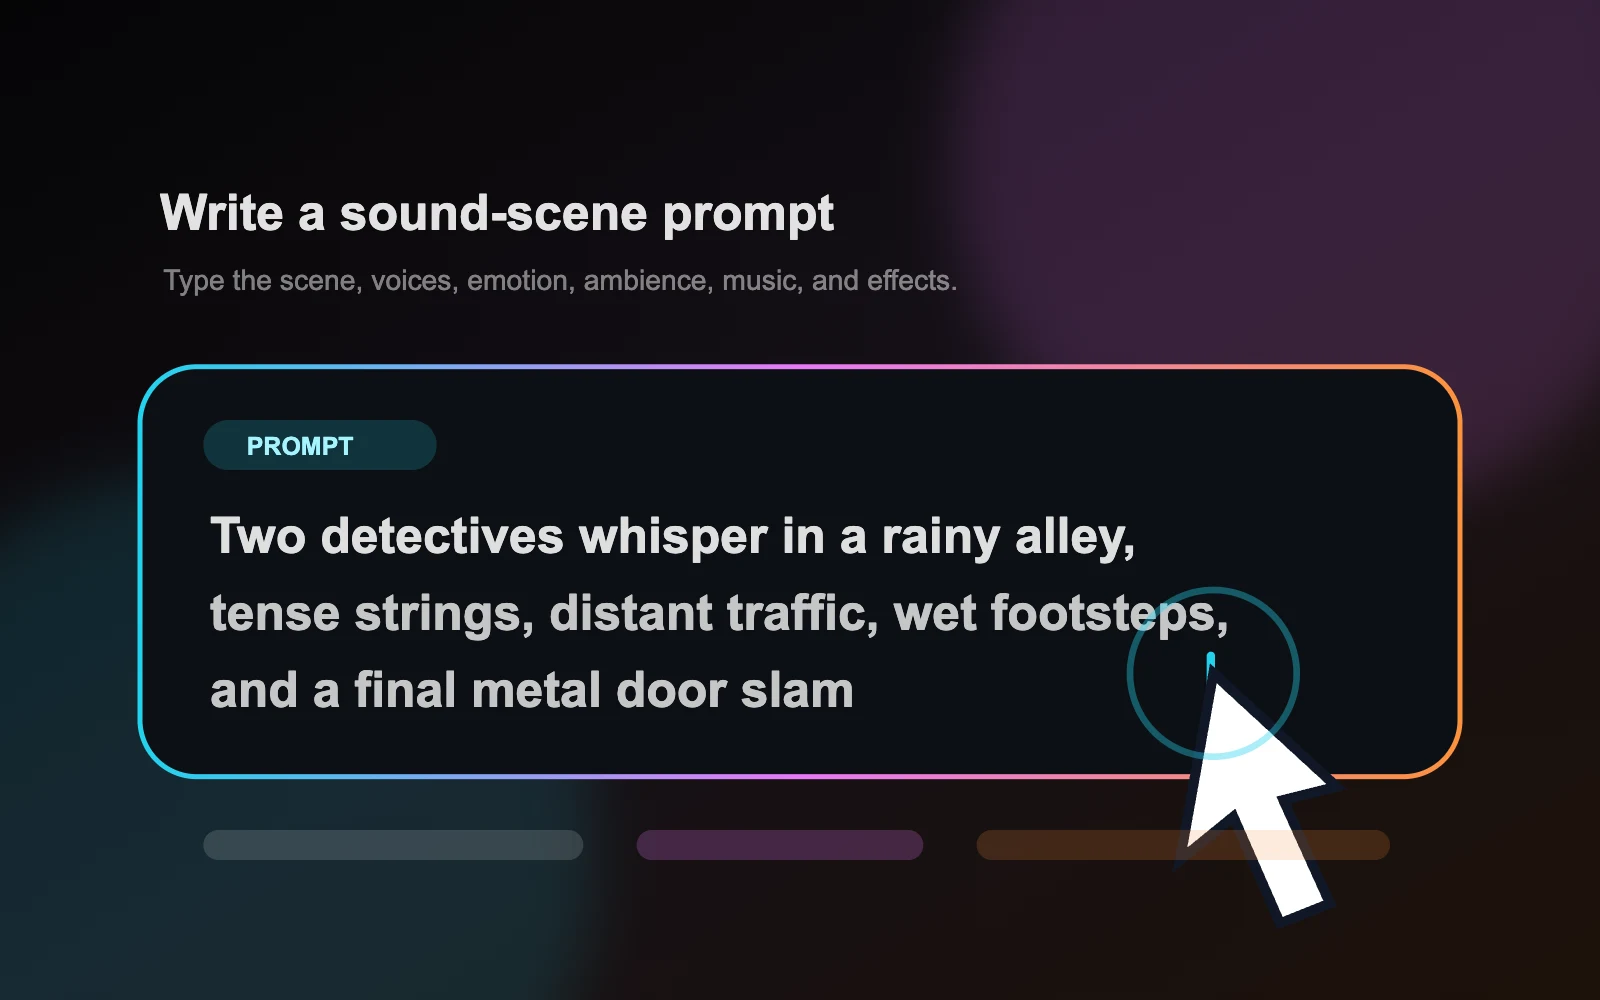
Describe the characters, language, emotion, location, dialogue, ambience, music direction, and sound events you want in the scene.
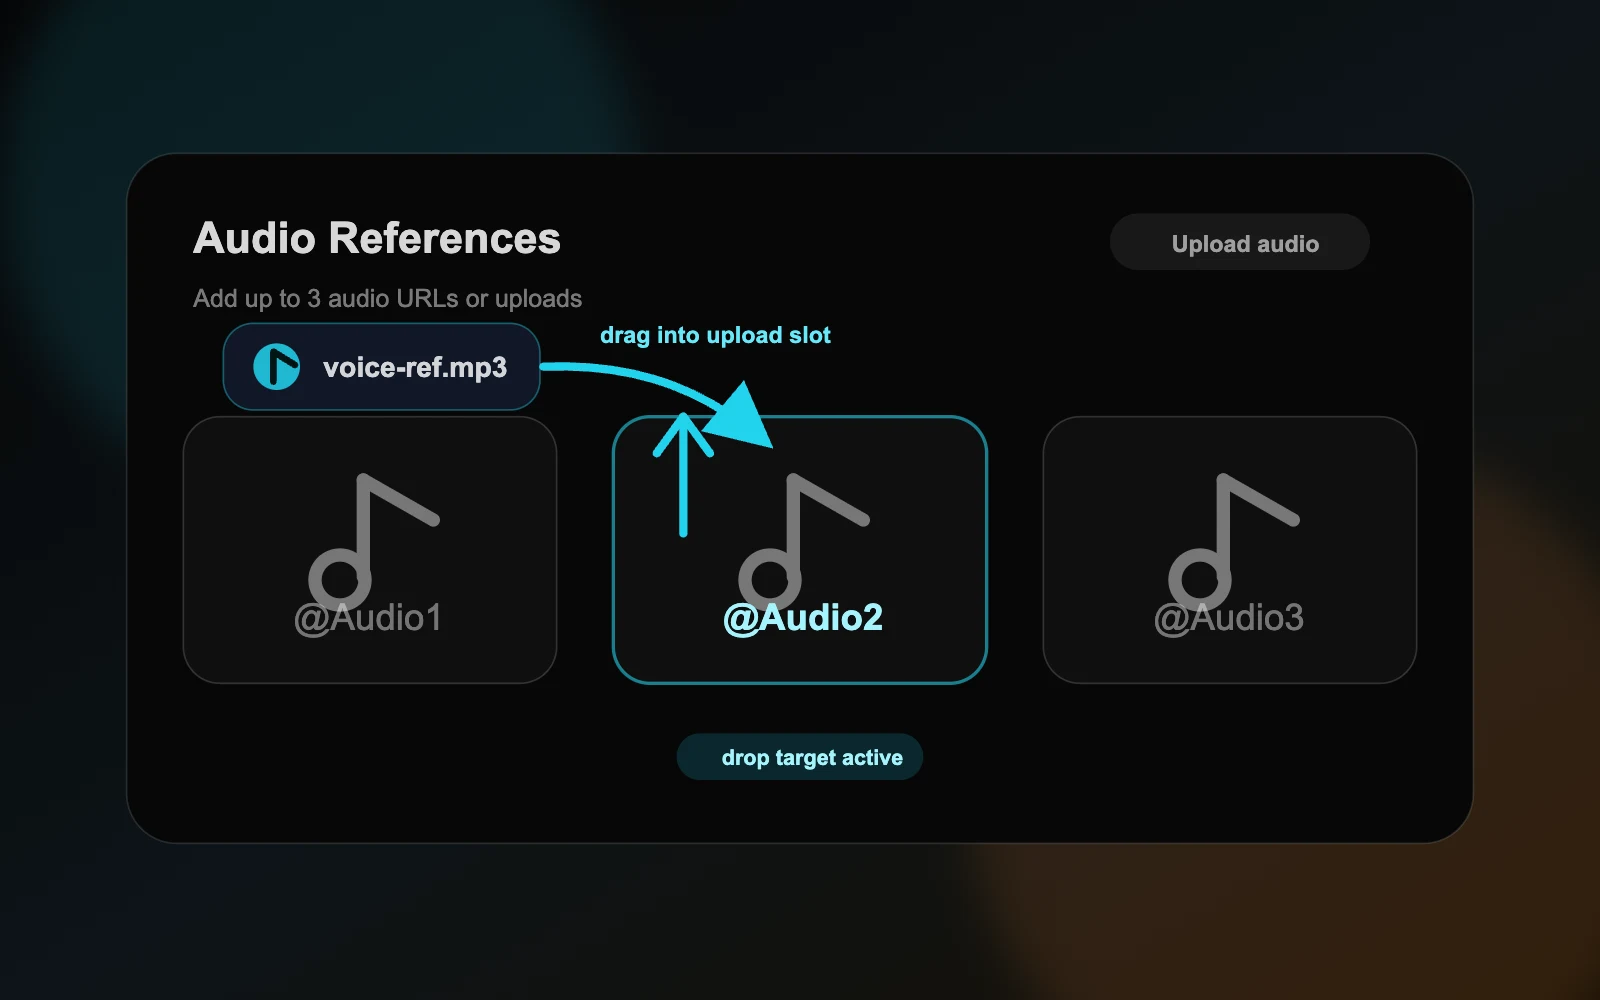
The live Seed Audio 1.0 generator accepts up to three audio references or one image. Published SeedAudio 1.5 support goes to six audio references and adds video-aware input.
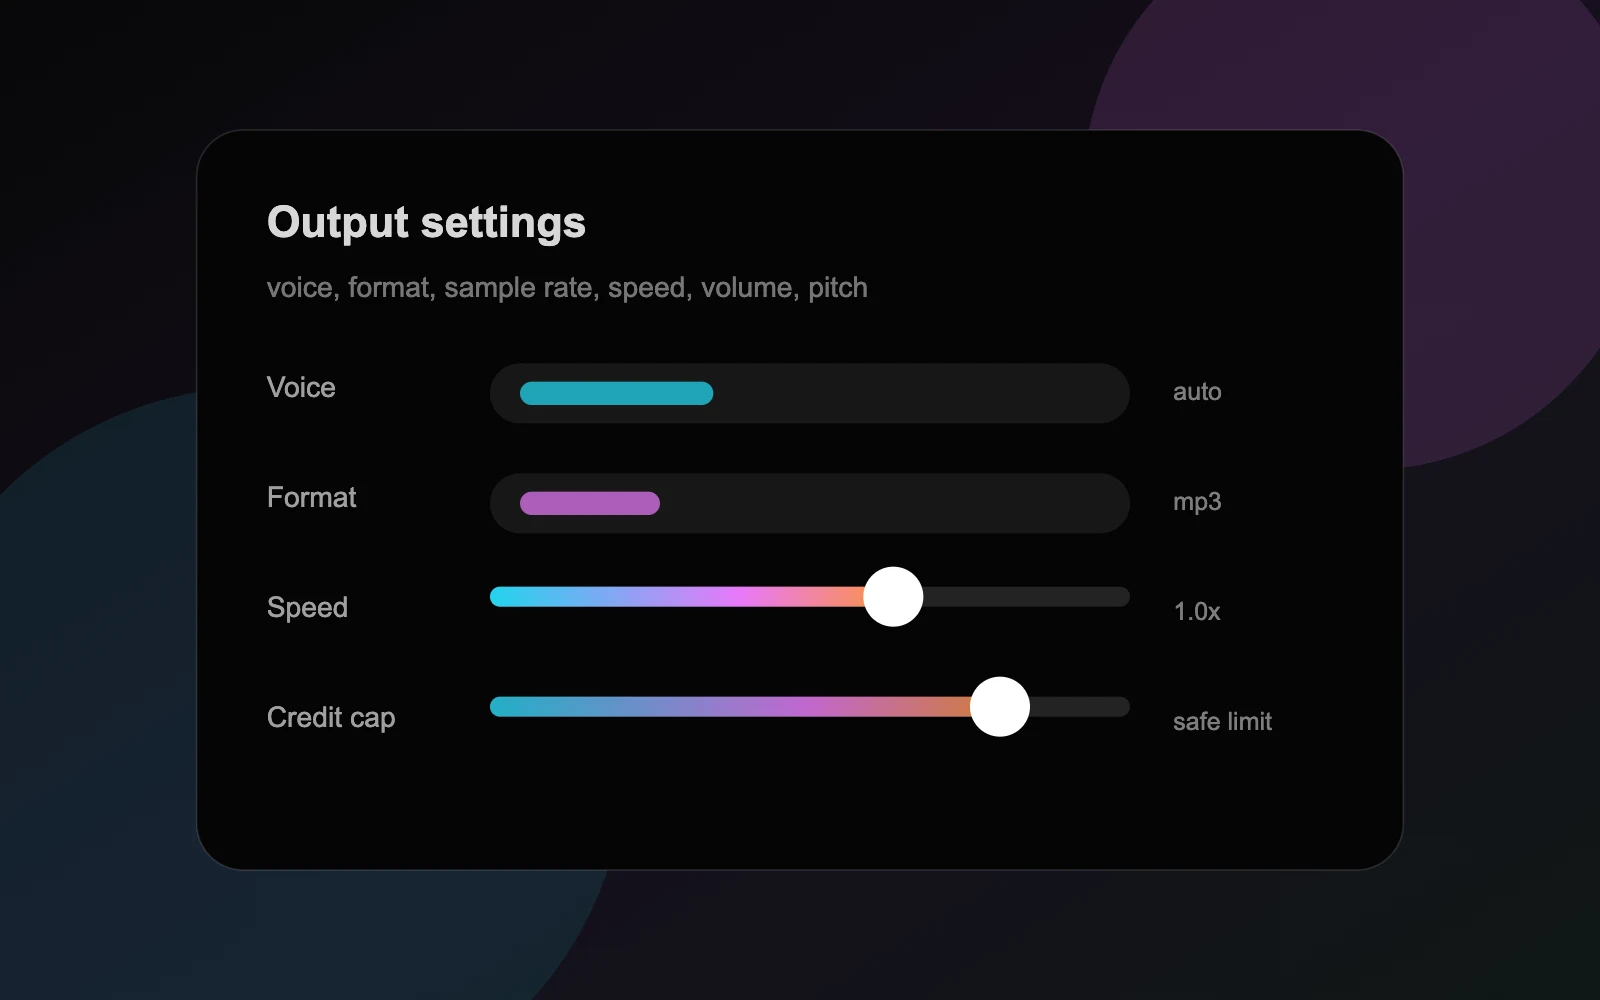
Pick voice behavior, output format, sample rate, speed, volume, pitch, and a max credit cap before running the generation.
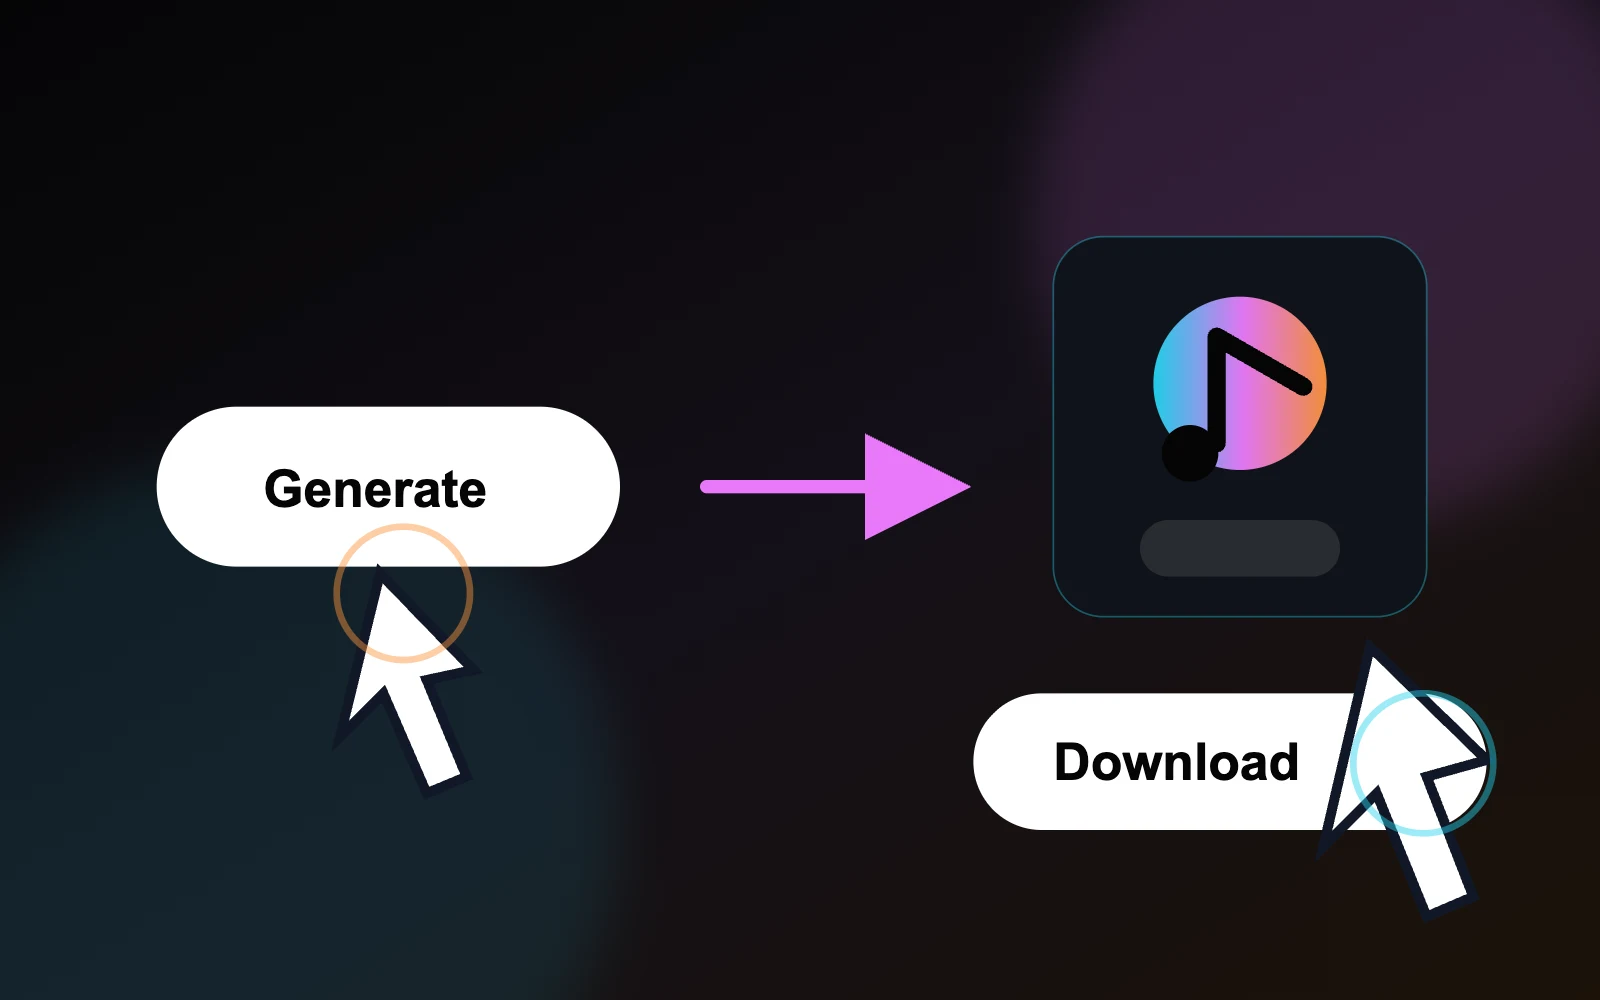
Run a short draft first, listen for voice clarity and layer balance, then copy, download, or revise the result.
Prompt formula
Scene + speaker + emotion + language + ambience + BGM + sound effects + timing.
Pricing
SeedAudio 1.5 is coming soon. Order now to lock in early-bird pricing. Plan prices are unchanged. Credits work today on the Seed Audio 1.0 generator and stay on one shared balance for the web app and API.
See SeedAudio 1.5 pricingTry Seed Audio 1.0 with free signup credits. Perfect for testing prompts and short scenes.
The best annual choice for creators with ongoing audio needs.
The strongest value for teams that expect heavy audio generation.
FAQs
Answers about SeedAudio 1.5, the current Seed Audio 1.0 generator, and early-bird pricing.
Order now for early-bird pricing. The generator still runs Seed Audio 1.0, so you can create sound scenes while seed-audio-1.5 is on the way.